How to download background genes from NCBI
Example
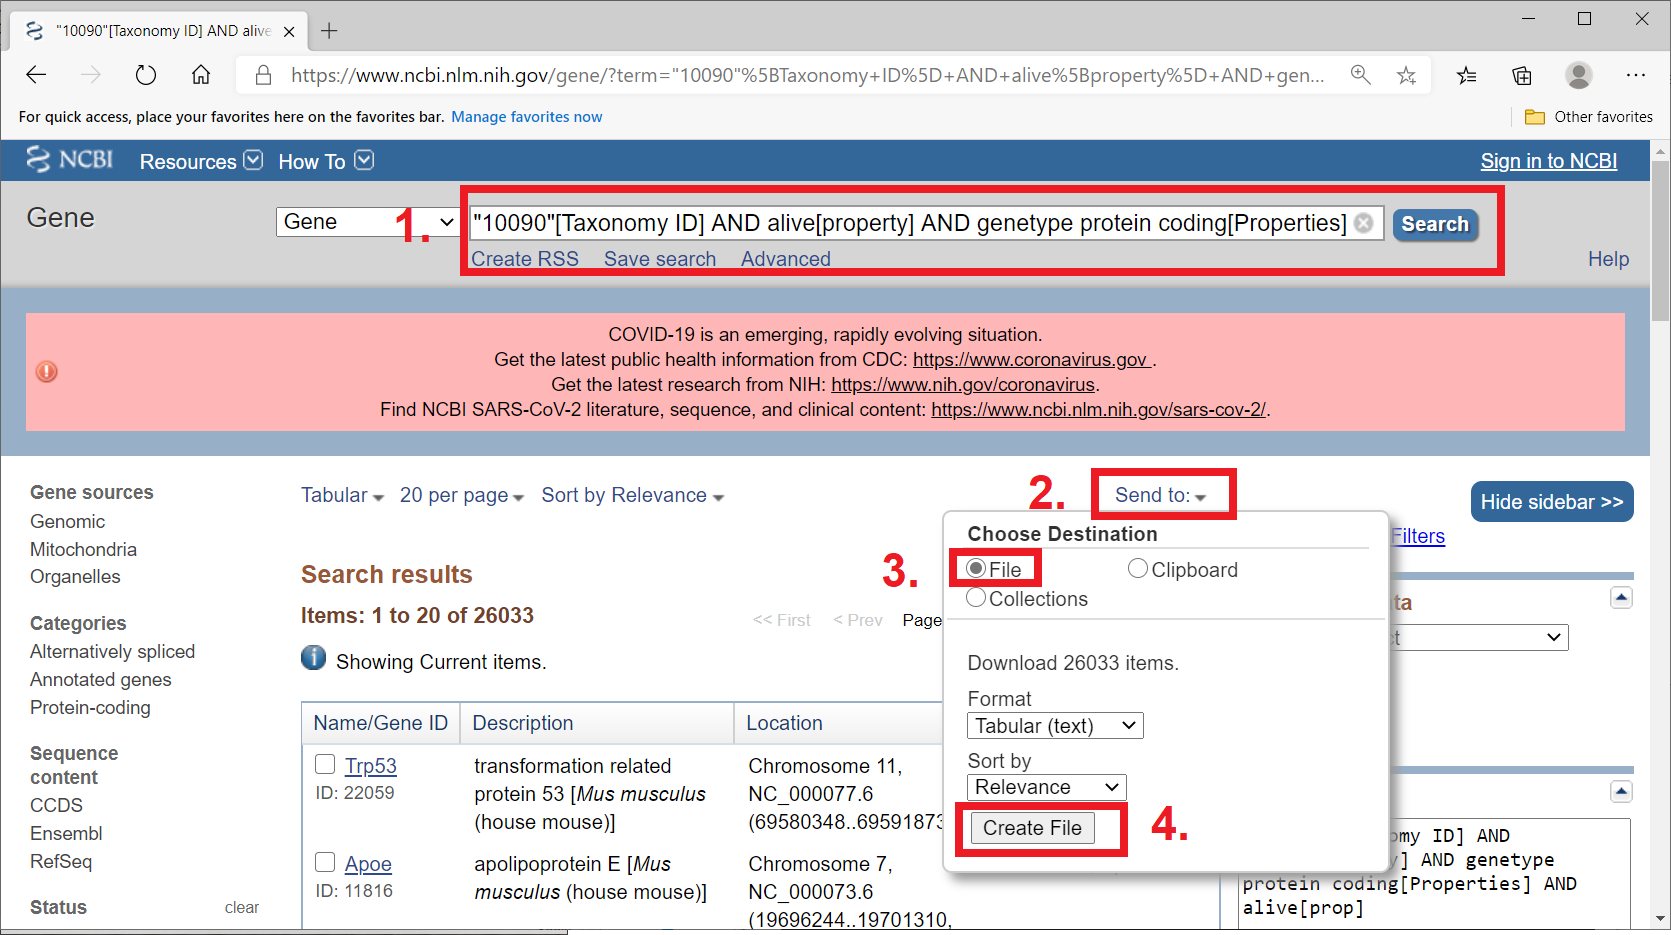
1) Download mouse (TaxID=10090) protein-coding genes
Query NCBI Gene:
"10090"[Taxonomy ID] AND alive[property] AND genetype protein coding[Properties]Click “Send to:”
Select “File”
Select “Create File” button The default name of the tsv file is
gene_result.txt
Note: To download all mouse DNA items:
"10090"[Taxonomy ID] AND alive[property]
2) Convert NCBI Gene tab separated values (tsv) file to a Python module
Use the command line or a Python script to convert a NCBI Gene tsv file to a Python module
2a) Run a script from the command line
$ goatools ncbi_gene_results_to_python gene_result.txt -o genes_ncbi_10090_proteincoding.py
      26,386 lines READ:  gene_result.txt
      26,376 geneids WROTE: genes_ncbi_10090_proteincoding.py
2b) Run a function from inside your Python script
from goatools.cli.ncbi_gene_results_to_python import ncbi_tsv_to_py

ncbi_tsv = 'gene_result.txt'
output_py = 'genes_ncbi_10090_proteincoding.py'
ncbi_tsv_to_py(ncbi_tsv, output_py)
      26,386 lines READ:  gene_result.txt
      26,376 geneids WROTE: genes_ncbi_10090_proteincoding.py
3) Explore NCBI gene data
3a) Import NCBI data from new NCBI gene Python module
from genes_ncbi_10090_proteincoding import GENEID2NT
3b) Examine fields stored in a namedtuple for a gene
# Get the data for one gene
nt_gene = next(iter(sorted(GENEID2NT.values())))

# Print the field name and value for all fields for one gene
for key, val in sorted(nt_gene._asdict().items()):
    print('{:15} {}'.format(key, val))
Aliases         ['A1m', 'A2m', 'AI893533', 'MAM']
CurrentID       0
GeneID          11287
OMIM            []
Org_name        Mus musculus
Status          live
Symbol          Pzp
chromosome      6
description     PZP, alpha-2-macroglobulin like
end_position_on_the_genomic_accession 128503683
exon_count      36
genomic_nucleotide_accession_version NC_000072.7
map_location    6 63.02 cM
no_hdr0
orientation     minus
other_designations pregnancy zone protein|alpha 1 macroglobulin|alpha-2-M|alpha-2-macroglobulin
start_position_on_the_genomic_accession 128460530
tax_id          10090
3c) Get genes which have specific genomic locations
nts = [nt for nt in GENEID2NT.values() if nt.start_position_on_the_genomic_accession != '']
nts = sorted(nts, key=lambda nt: nt.GeneID)
print('{N:,} genes have specific genomic basepair locations'.format(N=len(nts)))
22,216 genes have specific genomic basepair locations
3d) Print GeneID, Symbol, and description of some genes
print('GeneID Symbol   Description')
print('------ -------  --------------------------------------------------------')
for nt_gene in nts[:20]:
    print('{GeneID:6} {Symbol:8} {description}'.format(**nt_gene._asdict()))
GeneID Symbol   Description
------ -------  --------------------------------------------------------
 11287 Pzp      PZP, alpha-2-macroglobulin like
 11298 Aanat    arylalkylamine N-acetyltransferase
 11302 Aatk     apoptosis-associated tyrosine kinase
 11303 Abca1    ATP-binding cassette, sub-family A (ABC1), member 1
 11304 Abca4    ATP-binding cassette, sub-family A (ABC1), member 4
 11305 Abca2    ATP-binding cassette, sub-family A (ABC1), member 2
 11306 Abcb7    ATP-binding cassette, sub-family B (MDR/TAP), member 7
 11307 Abcg1    ATP binding cassette subfamily G member 1
 11308 Abi1     abl interactor 1
 11350 Abl1     c-abl oncogene 1, non-receptor tyrosine kinase
 11352 Abl2     v-abl Abelson murine leukemia viral oncogene 2 (arg, Abelson-related gene)
 11354 Scgb1b27 secretoglobin, family 1B, member 27
 11363 Acadl    acyl-Coenzyme A dehydrogenase, long-chain
 11364 Acadm    acyl-Coenzyme A dehydrogenase, medium chain
 11370 Acadvl   acyl-Coenzyme A dehydrogenase, very long chain
 11409 Acads    acyl-Coenzyme A dehydrogenase, short chain
 11416 Slc33a1  solute carrier family 33 (acetyl-CoA transporter), member 1
 11418 Asic2    acid-sensing (proton-gated) ion channel 2
 11419 Asic1    acid-sensing (proton-gated) ion channel 1
 11421 Ace      angiotensin I converting enzyme (peptidyl-dipeptidase A) 1
3e) Create a symbol2nt dict
sym2nt = {nt.Symbol:nt for nt in nts}
print('{N:,} gene symbols'.format(N=len(sym2nt)))
assert len(nts) == len(sym2nt)
22,216 gene symbols
3f) Print NCBI information for a specific gene
# Choose a specific gene
symbol = 'Ace'

# Print NCBI information for the chosen gene
for field, value in sorted(sym2nt[symbol]._asdict().items()):
    print('{FLD:15} {VAL:}'.format(FLD=field, VAL=value))
Aliases         ['AW208573', 'CD143']
CurrentID       0
GeneID          11421
OMIM            []
Org_name        Mus musculus
Status          live
Symbol          Ace
chromosome      11
description     angiotensin I converting enzyme (peptidyl-dipeptidase A) 1
end_position_on_the_genomic_accession 105880790
exon_count      26
genomic_nucleotide_accession_version NC_000077.7
map_location    11 68.84 cM
no_hdr0
orientation     plus
other_designations angiotensin-converting enzyme|dipeptidyl carboxypeptidase I|dipeptidyl peptidase|kininase II
start_position_on_the_genomic_accession 105858774
tax_id          10090
Copyright (C) 2016-present, DV Klopfenstein, H Tang. All rights reserved.